- Startseite /
- Bücher /
- Computer und Technologie /
- Informatik /
- AI & Machine Learning /
- Intelligence & Semantics /
- Lessons from AlphaZero for Optimal, Model Pre...
0 ratings


Artikelnr.:
184458100
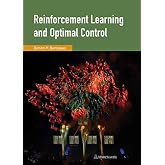
Lessons from AlphaZero for Optimal, Model Predictive, and Adaptive Control
86% der Befragten würden dies einem Freund empfehlen
Artikelnr.:
184458100
€ 67
Price Details
Ohne Versand- und Zollkosten ( Versand- und Zollkosten werden an der Kasse berechnet )
*Alle Artikel werden aus USA importiert
0 ratings
Schreiben Sie eine Bewertung
Auf Lager
 Vom USA Store für Sie importiert
QTY:
Nur noch 4 Artikel auf Lager.
Bestellen Sie jetzt und erhalten Sie es am Monday, Oktober 26
Gesicherte Transaktion
Ubuy ist bestrebt, Ihre Sicherheit und Privatsphäre zu schützen. Unser fortschrittliches Zahlungssicherheitssystem gewährleistet Vertraulichkeit, indem Ihre Daten während der Übertragung mit AES (Advanced Encryption Standards) und SSL (Secure Socket Layer) Protokollen verschlüsselt werden. Ihre Zahlungsdaten sind 100% sicher, da wir Ihre Zahlungsdaten nicht an Drittanbieter weitergeben.
Unsere besten Logistigpartner


This book proposes a revolutionary framework that enhances reinforcement learning through the synergy of off-line training and on-line play algorithms.

Fast
Shipping

Kostenlose
Rücksendung*

Sichere Verpackung

100 % Originalprodukte

PCI DSS-Standards

ISO 27001-zertifiziert



Note: Step Down Voltage Transformer required for using electronics products of USA store (110-120). Recommended power converters Jetzt kaufen.


Besondere Merkmale
Advanced Learning Techniques
Utilizes cutting-edge reinforcement learning methods to optimize control strategies, ensuring learning from vast data inputs for precise performance.
Model Predictive Control
Incorporates model predictive control to enhance predictive accuracy, enabling proactive decision-making in dynamic environments and improving control efficiency.
Adaptive Strategies
Features adaptive control mechanisms that adjust to changing conditions, ensuring robust system performance across varying scenarios while minimizing manual interventions.
Produktdetails
- The purpose of this book is to propose and develop a new conceptual framework for approximate Dynamic Programming (DP) and Reinforcement Learning (RL). This framework centers around two algorithms, which are designed largely independently of each other and operate in synergy through the powerful mechanism of Newton's method. We call these the off-line training and the on-line play algorithms; the names are borrowed from some of the major successes of RL involving games. Primary examples are the recent (2017) AlphaZero program (which plays chess), and the similarly structured and earlier (1990s) TD-Gammon program (which plays backgammon). In these game contexts, the off-line training algorithm is the method used to teach the program how to evaluate positions and to generate good moves at any given position, while the on-line play algorithm is the method used to play in real time against human or computer opponents. Both AlphaZero and TD-Gammon were trained off-line extensively using neural networks and an approximate version of the fundamental DP algorithm of policy iteration. Yet the AlphaZero player that was obtained off-line is not used directly during on-line play (it is too inaccurate due to approximation errors that are inherent in off-line neural network training). Instead a separate on-line player is used to select moves, based on multistep lookahead minimization and a terminal position evaluator that was trained using experience with the off-line player. The on-line player performs a form of policy improvement, which is not degraded by neural network approximations. As a result, it greatly improves the performance of the off-line player. Similarly, TD-Gammon performs on-line a policy improvement step using one-step or two-step lookahead minimization, which is not degraded by neural network approximations. To this end it uses an off-line neural network-trained terminal position evaluator, and importantly it also extends its on-line lookahead by rollout (simulation with the one-step lookahead player that is based on the position evaluator). Significantly, the synergy between off-line training and on-line play also underlies Model Predictive Control (MPC), a major control system design methodology that has been extensively developed since the 1980s. This synergy can be understood in terms of abstract models of infinite horizon DP and simple geometrical constructions, and helps to explain the all-important stability issues within the MPC context. An additional benefit of policy improvement by approximation in value space, not observed in the context of games (which have stable rules and environment), is that it works well with changing problem parameters and on-line replanning, similar to indirect adaptive control. Here the Bellman equation is perturbed due to the parameter changes, but approximation in value space still operates as a Newton step. An essential requirement here is that a system model is estimated on-line through some identification method, and is used during the one-step or multistep lookahead minimization process. In this monograph we aim to provide insights (often based on visualization), which explain the beneficial effects of on-line decision making on top of off-line training. In the process, we will bring out the strong connections between the artificial intelligence view of RL, and the control theory views of MPC and adaptive control. Moreover, we will show that in addition to MPC and adaptive control, our conceptual framework can be effectively integrated with other important methodologies such as multiagent systems and decentralized control, discrete and Bayesian optimization, and heuristic algorithms for discrete optimization. One of our principal aims is to show, through the algorithmic ideas of Newton's method and the unifying principles of abstract DP, that the AlphaZero/TD-Gammon methodology of approximation in value space and rollout applies very broadly to deterministic and stochastic optimal control problems. Newton's method here is used for the solution of Bellman's equation, an operator equation that applies universally within DP with both discrete and continuous state and control spaces, as well as finite and infinite horizon.
| Publisher | Athena Scientific |
| Publication date | March 19, 2022 |
| Language | English |
| Print length | 211 pages |
| ISBN-10 | 1886529175 |
| ISBN-13 | 978-1886529175 |
| Item Weight | 1.05 pounds (480 grams) |
| Dimensions | 10 x 8 x 2 inches (25.4 x 20.3 x 5.1 cm) |
Für wen ist das Produkt geeignet?

-
Control Engineers
Ideal for control engineers seeking advanced techniques in optimal and model predictive control for complex systems.
-
Researchers
Beneficial for researchers focusing on adaptive control and machine learning methodologies in modern control systems.
-
Graduate Students
Perfect for graduate students studying control theory who want to deepen their understanding through practical applications.

-
Non-technical Users
Not suitable for non-technical users or those without a background in control systems or mathematics.
PRODUKTBESCHREIBUNG
Haben Sie eine Frage? Mit uns chatten
Kundenfragen und -antworten
-
Frage:
Wie kaufe ich Lessons from AlphaZero for Optimal, Model online bei Ubuy ein?
Antworten: Es ist ganz einfach, Lessons from AlphaZero for Optimal, Model online bei Ubuy einzukaufen.. Sie müssen nur nach dem Produkt suchen, beim Bezahlen Ihre Versandart auswählen und es an Ihren Standort liefern lassen. -
Frage:
Ist Lessons from AlphaZero for Optimal, Model in Austria zum Online-Shoppen verfügbar?
Antworten: Ja, bei Ubuy Austria können Sie dieses Produkt zu einem angemessenen Preis kaufen.. Das Lessons from AlphaZero for Optimal, Model ist lokal nicht verfügbar, aber Sie können uns unseren Expressversandservice anvertrauen. -
Frage:
Wie lange dauert es nach der Bestellung, bis ich das Produkt erhalte?
Antworten: Die Lieferzeit Ihres bestellten Produkts hängt davon ab, was Sie bestellt haben und welche Versandart Sie gewählt haben.. Die voraussichtliche Lieferzeit wird während des Bestellvorgangs angegeben. Seien Sie also beim Einkaufen unbesorgt.
Intelligence & Semantics Editorial Review
Lessons from AlphaZero for Optimal, Model Predictive, and Adaptive Control is a captivating read published by Athena Scientific on March 19, 2022. This book, containing 211 pages of insightful content, delves into advanced control techniques influenced by the groundbreaking AlphaZero AI. Readers have praised its clear language and structured approach, making complex topics more accessible. The book's comprehensive coverage is ideal for both students and professionals interested in AI applications in control systems. Its dimensions are 10 x 8 x 2 inches, making it a solid yet portable resource for enthusiasts eager to enhance their understanding of model predictive control and adaptive control methods.
Kundenbewertungen
2 Kundenbewertungen
-
5 Sterne
100%
-
4 Sterne
0%
-
3 Sterne
0%
-
2 Sterne
0%
-
1 Sterne
0%
Bewerten Sie dieses Produkt
Teilen Sie Ihre Meinung mit anderen Kunden
Vorteile
- Well-structured and easily understandable content
- Focuses on AI applications in control systems
- Comprehensive resource for students and professionals
- Clear explanations of complex techniques
- Portable size for easy reading
Nachteile
- Some readers may prefer more advanced topics covered
Produktpreisverlauf
Wichtige Information
- Einschränkungen: Für international versandte Produkte beachten Sie bitte, dass jegliche Herstellergarantie nicht gültig sein könnte; Herstellerservice-Optionen nicht verfügbar sein könnten; Produkthandbücher, Gebrauchsanleitungen und Sicherheitshinweise nicht in der Sprache des Ziellandes verfasst sein könnten; die Produkte (und Begleitmaterialien) könnten nicht im Einklang mit den Standards, Spezifizierungen und Etikettierungsvorgaben des Ziellandes entworfen sein; und die Produkte könnten nicht der Voltzahl und anderen elektrischen Standards des Ziellandes entsprechen (weshalb, falls zutreffend, die Verwendung eines Adapters oder Umwandlers erforderlich sein könnte). Der Empfänger ist dafür verantwortlich sicherzustellen, dass das Produkt legal in das Zielland importiert werden kann. Bei der Bestellung von Ubuy oder seinen Partnern ist der Empfänger der eingetragene Importeur und muss sich an alle Gesetze und Regulierungen des Ziellandes halten.
- Nicht alle auf Ubuy aufgeführten Produkte werden zum Verkauf angeboten, da Ubuy eine globale Suchmaschine ist. Produkte unterliegen Export-/Handelsbestimmungen.
€ 67
Bestellen Sie jetzt und erhalten Sie es am Monday, Oktober 26
Dieser Artikel unterliegt in meinem Land keinen Beschränkungen. (Klicken Sie bitte auf den obigen Link, wenn dieser Artikel in Ihrem Land keinen Beschränkungen unterliegt. Unser Team wird ihn dann prüfen und zulassen.)
QTY:
Nur noch 4 Artikel auf Lager.
Gesicherte Transaktion
PCI DSS compliant and ISO 27001:2022 certified, with encrypted payments and full buyer protection on every order.
Unsere besten Logistigpartner
Schnellste grenzüberschreitende Lieferung
Merkmale und Vorteile
- Revolutionary framework for Dynamic Programming and Reinforcement Learning.
- Synergy between off-line training and on-line play algorithms.
- Inspired by successful programs like AlphaZero and TD-Gammon.
- Improves performance through policy improvement without neural network degradation.
- Applicable to Model Predictive Control systems for enhanced stability.
- Adapts to changing problem parameters and effective online replanning.
Ubuy Assurance
Experience worry-free shopping with 100% original products, PCI DSS-compliant payment security, ISO 27001-certified data protection, the fastest cross-border delivery, free returns *, and secure packaging on every order.